A confidence score is not a promise.
From the creator of laya, the first open source System 1 decision model, trained with the first open source reinforcement learning for calibrated decisions.
Embedding Studio fits a decision model to cases your own team already decided, then measures what its answers are worth on rows nothing was fitted on. When no answer clears the bar, it returns nothing.
Built on a System 1 decision model. Fit it, calibrate it, hold it to a number.
The same record, before and after
“I was billed twice, refund me or I cancel.”
Question: Does the customer threaten to leave or cancel? Yes. “or I cancel” is the customer threatening to leave.
Out of the box
- answer
- no
- conf.
- 0.9975
- shortlist
- no shortlist
Confidently wrong. Your code reads the top answer and acts on it.
After fit and calibrate
- answer
- no
- conf.
- 0.677
- shortlist
- both answers on the shortlist
Both answers are live, so nothing is automated and a person picks it up.
A real run on the shipped 0.8B reader. The calibration behind the second row was fitted on fourteen labelled rows, which is the point: it takes very little to stop a model being confidently wrong.
As a cloud API
POST /v1/projects/<slug>/decide
X-API-Key: esk_...
{"text": "...", "idempotency_key": "..."}

-> route: auto | review, plus an audit block
One call. The response carries a route field your code branches on, so there is no threshold for you to invent.
On your own hardware
# download calibration.json from the Studio
pip install 'vegaml[serve]'
vegaml-serve --calibration calibration-<version>.json \
             --threads 1 --preload

-> same decisions, no account, no network
The calibration is a file you keep: the temperature, the conformal threshold and the band. It is checksummed, so an edited file stops matching its own version and the engine refuses it.
34,431
GitHub stars on laya
77,863
downloads on the Hub
6,452
Hugging Face likes
1,363
points on Hacker News
33 ms
median per decision
51
languages measured
Stars, downloads and likes read live from GitHub and Hugging Face, re-read every minute. Downloads and likes are summed over laya, laya-multilingual, laya-typed-decisions, vega-08b-public-intents and vega-U.
Integrated, ported, benchmarked and studied across the ecosystem
 Hugging Face
 vLLM Semantic Router
 Receptron
 innFactory
 ZimaSpace
 daily.dev
Every name links to the public integration, port, benchmark or write up it stands for. Drag, scroll, or use the arrows.
Embedding Studio
Your own decided cases in, a calibrated decision out.
A model that answers everything is a model you cannot automate with, because you never learn which answers to act on. Embedding Studio fits to the way your team already decides, measures the result on a slice it never touched, and hands back an answer with a number attached that somebody can be held to.
A coverage guarantee you set
Conformal prediction turns your held-back rows into one threshold, and the promise that comes with it is yours to choose: right 9 times in 10, or 99 in 100, with the shortlist widening as you ask for more. A confidence score on its own carries no such promise.
The right to answer nothing
When no option clears the threshold the answer is empty, and your code cannot act on it because there is nothing in the field to act on. That is a different thing from a low number you remembered to check.
A review rate known before you ship
The band reports what share of traffic needs a person at your target precision, measured on rows nothing was fitted on. You staff against a number rather than discovering it in production.
The calibration is a file you keep
What the fit produces is a calibration.json you can download, and it is the whole artifact: the temperature, the conformal threshold and the band. Hand it to the open source engine and the same decisions run on your own hardware, offline, with no account and nothing calling home. Cancel the subscription and the file still works.
Five steps, in the order you do them
1. Define
Write the questions you already answer by hand. Three kinds: a choice between options, a score, or yes and no. The wording is the specification, so it is yours rather than a public taxonomy.
2. Teach
One CSV of cases your team already decided. It is cut 60 / 20 / 20: the first slice fits, the second calibrates, the third is held back and never fitted on, and every number you are shown comes off that third slice.
3. Route
Pick the precision you need and the band tells you what share of traffic it can automate at that precision, measured, on a one-sided 95% lower bound. Ask for a precision nothing can hold and it says so rather than quietly shipping one that does not.
4. Deploy
One POST with a key. The answer carries a route field, auto or review, so the integration is a branch rather than a threshold you had to invent.
5. Watch
Population stability index on the mix of answers, which needs no labels. A calibration survives a covariate shift and breaks on a prior shift, so the mix is the thing worth watching.
0.160 to 0.069
calibration error, uncalibrated to calibrated, across six corpora
60 / 20 / 20
fit, calibrate, held back and never fitted on
0.816
what twelve correct out of twelve certifies, not 1.0
$0.0010
a decision, with $10 of credit to start
The measured numbers and what each one does and does not cover are in the docs. The request and response reference lives in the product's own documentation, because that is where it stays current.
The open families
laya, vega, and next: vega-U.
2026, the first family
laya
A 421M encoder with a decision head, trained with reinforcement learning against strictly proper scoring rules. Choice, score or yes and no, answered in one forward pass, in about 33 ms on a T4. A multilingual sibling covers 51 measured languages on CPU. Community owned, open for good.
pip install laya
2026, the second family
vega
Adapters on frozen Qwen3.5 backbones, in 0.8B and 4B. A probability on every option and an answer on every row, from 74 ms per decision. The benchmark notebook pins its library versions and reruns on two T4s in an afternoon.
pip install vegaml
The next series · weights public
vega-U
The universal adapter. One 14.3M decision engine in a shared space that any frozen LLM plugs into through a small linear port, from 0.8B to 27B, with no retraining of the engine and no fine-tuning of the reader.
How it works →
Measured, not promised
The numbers, with their sources attached.
Median latency per decision
laya measured on a T4, one question. vega and Jev measured in one run, same rows, Jev over its hosted API.
laya against Jev, accuracy
Jev figures are third party published, so sample sizes and prompts differ. ECE after temperature fitting: 0.081 against 0.246.
vega 4B against Jev, one run
3,841 decisions per system against the live endpoint. Jev wins raw accuracy. vega answers every row, with calibration the hosted model does not match. Lower is better for ECE and KL.
Full tables, harnesses and raw JSON: laya benchmarks / vega results · the write up
What the internet said
 Hacker News1,363 points · 319 comments↗
“I built non-autoregressive decision models with RL a year ago.”
 On Xthe line that went around the launch↗
“Jev's moat lasted two days.”
 eesel AIfrom the blog↗
“The open 33 ms decision model that can't hallucinate.”
 Threads@meta.ai↗
“laya, the open source answer to Jev. Runs on your laptop for zero dollars, data stays local.”
 Analytics India Magazinethe profile↗
“This Kerala engineer built the open source Jev alternative a year before the hype.”
 visrowon Medium↗
“I ran a 421 million parameter decision model inside a browser tab. No server, no API key.”
 r/LocalLLaMAlaunch thread↗
“Made the horizontal open source model for Jev.”
 Runwarefrom the blog↗
“Within hours the community had labeled it the open source Jev.”
Hacker NewsJev vs laya↗“Does an open weight decision model beat a hosted one?”
 FeSathe review↗
“The open source System 1 decision engine outperforming Jev on latency and calibration.”
Data Science in Your Pocketon Medium↗“Bye bye TypeScript Jev AI.”
Hacker Newsshow and tell↗“laya, an open decision model that plays Tetris by itself.”
Tuhin Sharmaon Medium↗“System 1 AI for multilingual classification on CPU.”
 arXiv2609.28940↗
“Jev and laya as System One decision layers for pentest agents.”
More coverage, dated and sourced, on the news page.
Why embedding exists
Most of what software asks a model is a decision, not an essay. Route this ticket. Flag this email. Pick this tool. We think those answers should come from small open models that return a typed result with an honest probability, run on your hardware, and never see your data leave the building.
laya proved the idea could be open. vega proved it could be measured, reproducibly, against the best hosted model in the category. vega-U makes the engine independent of the reader, so one calibrated decision layer serves whichever LLM you already run. Everything we build ships open: weights, training code, and every benchmark with the harness that produced it. The business is the hosted path, an API you pay for per decision or by subscription, and commercial licenses for vega and the models that follow. laya stays community-owned, open for good.
01 · Recursive language models
Depth on demand
A model that calls itself on the hard part of the problem, and stops when it is sure.
02 · Symbolic + abstract reasoning
Structure to settle over
Typed relations and programs, not prose. Calibration survives the abstraction.
03 · Beyond transformers
Dynamics, not attention alone
Continuous-time state and energy, attention only where it earns its memory.
classify → typed decisions → grounded reasoning → abstraction
Founder
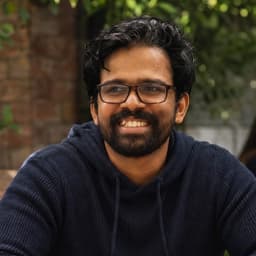
Nandakishor M
Builds small models that make decisions instead of writing essays about them. Founder of Convai Innovations, author of laya and vega, writing at nandakishorm.com.